Plan a pilot

One company brain for every team and
every AI assistant.

Why it exists

Every team and every assistant keeps its own copy.

Four teams and an assistant, each holding a different version of the same document.
TodayA change is explained five times, and the old version keeps being quoted.
One record in the middle, linked to every team and assistant.
With LoopwrightOne approved record. Everyone reads the same version.
Ask across the company

The problemAsk whether a Business customer can schedule an export, and Product, Support and Finance each answer from their own documents. The answers differ, and none says which one is current.

One question, answered from every team's records.

Pick a question. The answer names its records and its owner, or says nothing approved answers it.

Product

Scheduled exportsRule, version 2, planned
Who administers a workspaceDefinition
Exports for Business in Q1Goal

Engineering

Exports deploy flagOff until January 15
Data retentionPolicy

Support

Macro: setting up exportsApproved, version 1
Refund windowPolicy

Finance

Plan matrixDefinition
Invoice recordsNo rule on exports

Used in the answerDisagrees or has a gap
When a rule changes

The problemA rule changes in one place. The Support macro and the Finance plan matrix still say the old thing, and the help center bot keeps quoting it until a customer notices.

Change it once. See every record and assistant it touches.

Approve a new version. The records that now disagree are flagged, and every assistant is asked again.

Scheduled exports: who can use them
Version 1 is approved: Enterprise plan only.
The company brain around one ruleThe rule sits in the middle, owned by Product. It links to an Engineering deploy flag, a Support macro, a Finance plan matrix and the meeting where it was decided, and is read by two assistants and a custom app.
1. Approved once
2. Disagreements flagged
3. Assistants checked

Press the button to watch one change move through the brain. Example data from the product's own test scenario.

Every step is recorded

Agents can propose. Only people publish. The history of one rule, from proposal to proof.

Oct 2

Version 1 approved

Scheduled exports are available on the Enterprise plan only.
Nov 12

Version 2 proposed by an AI agent

- Scheduled exports are available on the Enterprise plan only.
+ Business plan customers, from January 15, 2027.
Nov 12

Published by the Product owner

ApprovedPlanned, not liveVersion 1 kept
Nov 12

Two approved records now disagree

Support macroFinance plan matrix
Nov 12

Assistants checked

Help center bot0 of 4 correctInternal assistant4 of 4 correct
Nov 12

Fixed and checked again

Help center bot4 of 4 correctInternal assistant4 of 4 correct
Who sees what

The problemPut every team's records in one place and the help center bot could quote Finance's internal notes, or someone who has left could still ask.

Same question, three readers, three answers.

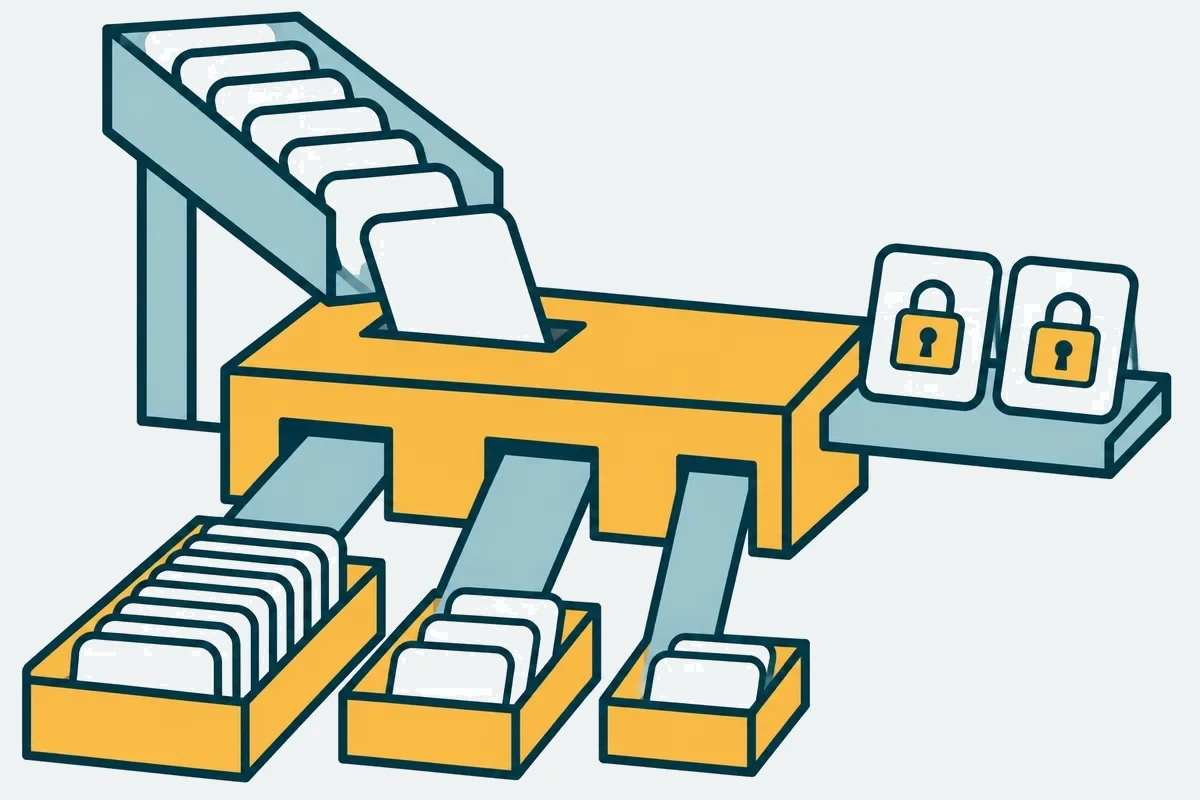
Access is applied when records are picked, before any prompt is built.

Records passing through a gate; some are let through and some are held back.

“Which plans include scheduled exports, and from when?”

Finance analyst

Company and Finance

Business, from January 15. Planned, not live. The plan matrix is flagged.

3 records in1 withheld

Help center bot

Customer-facing only

Business customers, from January 15. Planned, not available yet.

1 record in3 withheld

Removed member

Grant revoked

No answer. No access to the workspace.

0 records
Works with what you have

The problemYour assistants come from different vendors, and you learn what they say when a customer quotes it back to you.

Your assistants stay where they are.

Any vendor. They read approved text and get asked check questions.

get_contextget_recordsearchpropose_changepropose_app
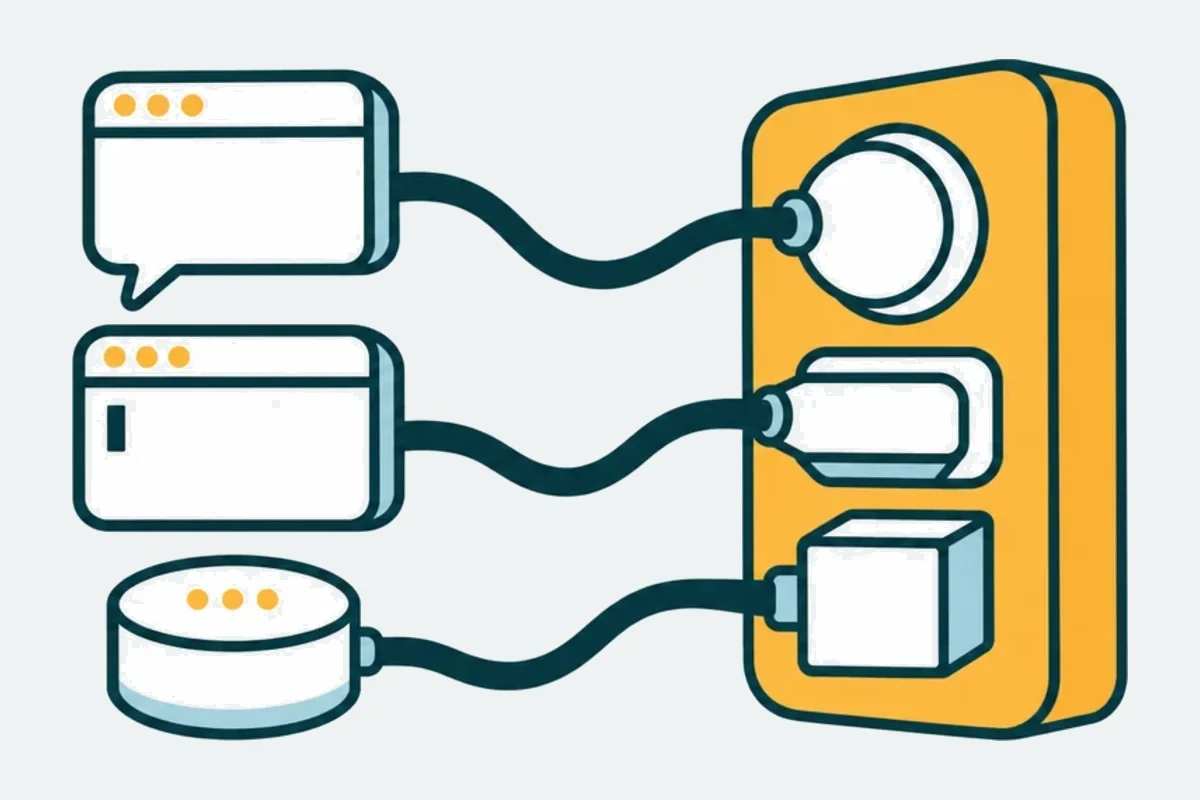
Three different assistants plugged into one shared source.
ReadMCPREST APIMarkdown or JSON export
Get checkedHTTPOpenAI-compatiblePasted by hand
$ loopwright check loopwright.checks.yaml

Help center bot             6 of 6 failed
  which-plans          FAIL  stale
  available-today      FAIL  overclaims
Product assistant           all 6 passed

check failed (--fail-on critical)

The check runner works alone in a release pipeline: no server, no account.

Features

Everything in the box today.

One server and one web app.

Department spaces

A space per team, with a named steward.

Records and versions

Rules, policies and definitions with an owner and a history.

Goals and meetings

Goals, decisions and actions as linked records.

Review queue

Anyone proposes. Only people publish.

Linked changes

Publishing flags the records that now disagree.

Checks

Ask every assistant before and after a change.

Ask and context

Answers with citations, over MCP and REST.

Access

Five roles and a grant per assistant.

Custom apps

Small HTML apps in a sealed frame.

Sources

Text, Markdown, HTML, PDF and Markdown in Git.

Workspaces

Several in one deployment, with a hard AI spending cap. Export and restore.

Sign-in

Email and password, invitations, tokens for clients.

Built and testedPartly being verified: goals and meetings screens, export and restore
How you know the controls hold

Tested in the open, not certified.

The tests ship with the source. No outside party has tested it yet.

Company isolation

Another company's identifiers return nothing.

Restricted text

A planted secret never reaches a prompt.

Revocation

Denied on the next request.

Propose, never publish

Agents and apps end with a proposal.

Sandbox escapes

Apps can't reach cookies or the network.

Planned is not live

Calling a planned feature available fails.

Limits today. Tests use a stand-in model, so answer quality on real providers is unmeasured.

Run it

Open source, on your servers.

One container beside your Postgres, with your model endpoint.
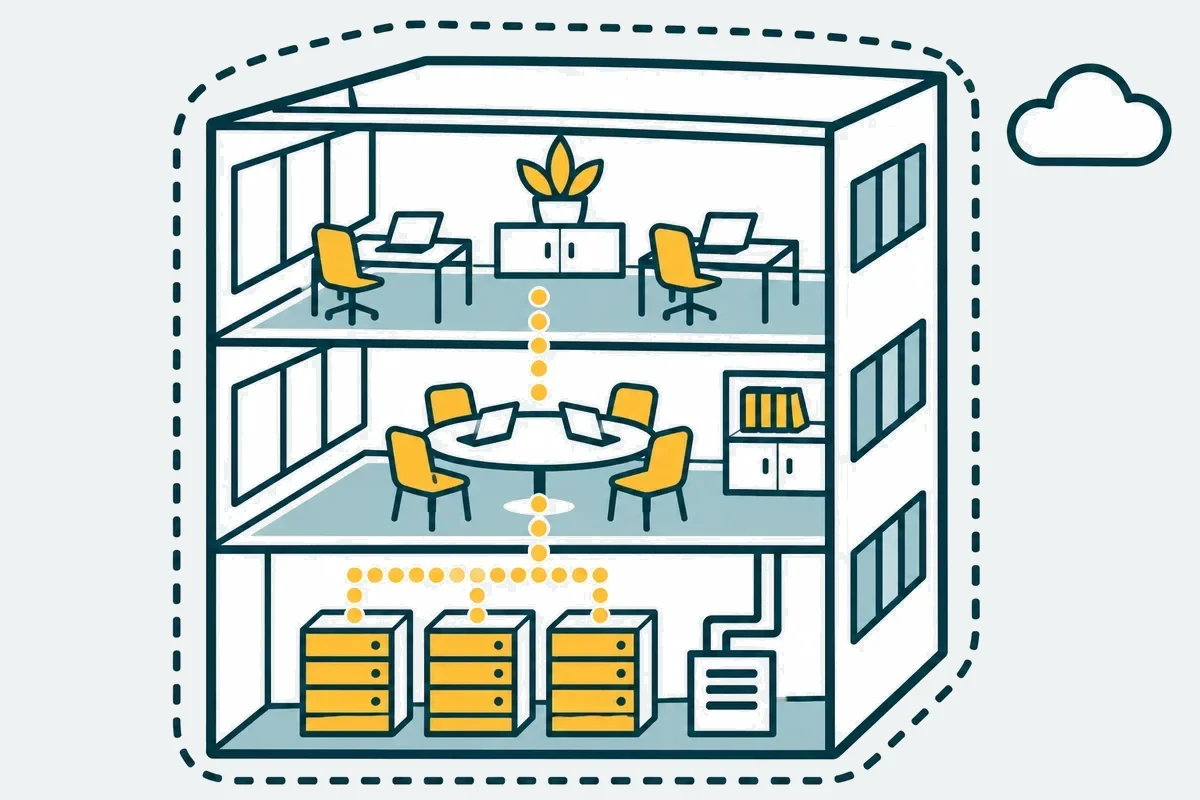
A server inside your own building, with the data staying inside.

Self-hosted

Postgres 16 with pgvectorDocker ComposeTwo required settingsLocal models workNo outside requests

Hosted Early access

The same server, run for you. No price or uptime commitment published yet.

What is built, being verified, and not built

Built and tested

  • Spaces, records, versions, review and publication
  • Goals, meetings, decisions and actions on the server
  • Access rules and row-level security
  • Context over REST and MCP, with tokens
  • Check runs, verdicts and automatic rechecks
  • Standalone check runner
  • Custom apps and their sandbox
  • Usage limits with a hard cap

Built, being verified

  • The container image with the web app
  • Workspace export and restore
  • Goals, meetings and Activity screens
  • S3-compatible file storage
  • OAuth sign-in for MCP clients; they use tokens today
  • Serving custom apps from a separate domain
  • A run against a live model

Not built

  • SSO and SCIM
  • SOC 2, ISO 27001 or any other certification
  • An independent security test
  • Audit trail file export
  • Region rules for model providers
  • Writing into assistants' knowledge sources
  • An OpenAPI document, and connectors beyond Git
  • Metrics, tracing and rate limiting
  • An uptime commitment or support terms
Tech stack

Boring parts, chosen so you can run it.

TypeScript throughout. One Postgres. No outside service required.

Web app

ReactTanStack RouterTanStack QueryTailwind CSS 4Radix UIVite

Assistants and apps

MCPREST APITyped clientSandboxed app frame

Server

Node.js 22TypeScriptHonoZodBetter Auth

Models

AI SDKAny OpenAI-compatible endpointOllama, vLLM, LM Studio

Data

Postgres 16pgvectorRow-level securityDrizzle ORMpg-boss

Delivery

Docker ComposeContainer imageS3-compatible storage

Outlined in marigold: built, being verified.

Packages and licences
@loopwright/serverAGPL 3.0
@loopwright/webAGPL 3.0
@loopwright/coreApache 2.0
@loopwright/checksApache 2.0
loopwrightApache 2.0
@loopwright/appApache 2.0
@loopwright/app-bridgeApache 2.0
@loopwright/uiApache 2.0

AGPL: run and modify it inside your company; publish changes if you offer it as a service. Apache: embed freely.

Questions

What teams ask first.

Is this a wiki or a search tool?

No. Records have an owner, a status and versions, and answers come only from the approved version. When nothing approved answers a question, it says so.

Do we have to replace our assistants or help center?

No. Assistants read over MCP or the REST API, or get approved text exported as Markdown or JSON.

Which models does it use?

Any OpenAI-compatible endpoint, including models on your own machines. The server also runs with no model.

Can an AI agent change a rule?

It can propose one, with evidence. Only a person publishes.

What does it cost?

Self-hosting is free under the open source licences. The hosted version is in early access with no published price.

Our company can't accept the AGPL. Is there another licence?

Not yet. Tell us, because it helps decide whether to offer one.

Do you support SSO, SCIM or have a SOC 2 report?

Not today. Loopwright is new, with no certifications and no customers to name.

Where is the source?

The public repository is not announced yet. Ask for source access and we will share it.

Bring one change and twenty questions.

We run it on your infrastructure and show what every assistant says, before and after.

info@loopwright.com